ATM Fleet Management: How to Fix Uptime, Cash Availability, and Operational Blind Spots
Posted on:
October 26, 2026
An ATM can be pinging the network perfectly but still be completely useless to your customer. It might be out of twenties, sitting with a jammed presenter, unable to complete a transaction, or waiting on a first-line maintenance (FLM) technician who was dispatched for what is clearly a second-line maintenance (SLM) issue.
That distinction matters because ATM fleet management is about much more than watching green and red dots on a monitoring dashboard. As fleets grow across mixed estates of NCR, Diebold Nixdorf, Hyosung, and other machines, ATM operations teams have to coordinate cash, Cash-in-Transit (CIT) movements, hardware lifecycles, maintenance providers, service-level agreements (SLAs), forecasting, and third-party vendors. Each function affects the others, but the systems managing them often do not.
Cash forecasting may sit in one application, terminal monitoring is handled somewhere else, service information lives in a vendor portal, and CIT schedules may be managed by another provider. Finance has its own reporting as well. When something goes wrong, operations teams are left assembling the full picture themselves, creating operational blind spots that make it harder to understand what is actually happening across the network.
Effective ATM fleet management requires more than visibility into individual events. It requires enough operational context to understand what those events mean, which ones need intervention, and what action should happen next. That means reducing unnecessary emergency cash runs, identifying recurring service failures, improving vendor accountability, and making decisions before an off-premise ATM cashes out immediately before a long holiday weekend.
The Operational Reality of ATM Fleet Management
ATM fleet management is the process of monitoring, maintaining, and operating a network of ATMs to maintain availability, optimise cash holdings, control servicing costs, and meet contractual service levels.
Depending on the operating model, that can involve:
• Moving from manual status monitoring to exception-based alerting.
• Using dynamic cash forecasting and CIT planning to reduce cash-outs, excess residual cash, and unnecessary replenishment costs.
• Giving field technicians access to fault and service histories to improve first-time fix rates and reduce repeat calls.
• Managing mixed technology environments and ageing hardware across the ATM estate.
• Tracking vendor performance and SLA compliance across service providers.
• Connecting ATM performance, transaction demand, service activity, and operating costs to support better lifecycle and replacement decisions.[AB2.1]
Managing 50 terminals may still leave room for manual intervention and spreadsheets, but managing a 500-node or 5,000-node fleet introduces a very different level of complexity. A larger network means more locations, more cash points, more complicated CIT routing, more maintenance activity, and a wider network of service providers. The estate itself may contain hardware from several manufacturers, different generations of terminals, different operating systems, and machines governed by different maintenance agreements.
At that point, even a simple "low cash" alert is not necessarily a simple decision. A low balance does not automatically mean the ATM should be replenished. Operations needs to know how much cash is left, how quickly that terminal normally dispenses it, whether demand is expected to increase, when the next scheduled CIT visit will occur, whether another nearby ATM can absorb demand, and whether changing the replenishment schedule will create additional cost.
Consider an ATM showing a low cash balance on Thursday afternoon. If historical behaviour suggests the remaining cash will comfortably support demand until a scheduled Monday replenishment, dispatching a vehicle early may be unnecessary. But if the same ATM sits near an event venue and demand typically doubles during weekend events, waiting until Monday could lead to a cash-out on Saturday. The balance may be the same, but the operational decision is not. That is the central challenge of ATM fleet management at scale: understanding the dependencies behind the status.
Why ATM Availability Is More Complicated Than "Uptime"
The Illusion of ATM Uptime
The industry frequently measures performance through uptime, but uptime alone rarely tells the whole story. An ATM can be powered, connected to the network, and technically online while still being unavailable for the transaction a customer wants to complete.
It may have no usable cash, a dispenser cassette may have failed, the card reader may be unavailable, or a presenter fault may prevent withdrawals. A peripheral issue may also have disabled part of the machine's functionality. From the network's perspective, the terminal is "up," but from the customer's perspective, it is not.
This is why ATM operators need to distinguish technical uptime from operational availability and dispensability. If the primary dashboard only indicates whether a machine has power and a network connection, operations teams can end up managing a technical metric rather than the customer outcome that matters. The more useful question is: Can the ATM successfully perform the transactions it is expected to perform right now? Answering that requires looking at multiple operational conditions together rather than relying on a binary online/offline status.
Availability Needs Context
A dispenser fault at 4:00 PM on a Friday illustrates the problem. Knowing that the dispenser has generated an error is useful, but it is only the starting point. Operations also needs to know whether the same unit experienced similar faults last week, whether the same component has already been repaired or replaced, which technician last worked on the terminal, whether an FLM intervention is appropriate, and how quickly the fault must be resolved to avoid a prolonged outage.
Service history turns a fault code into operational context. If the same ATM has jammed three times in the last month, treating the fourth incident as an isolated event is unlikely to solve the underlying problem. The pattern may indicate a recurring component failure, an installation issue, environmental conditions, or another problem that requires escalation beyond routine first-line maintenance.
This is where consolidated fleet data becomes particularly valuable. When availability, fault codes, service activity, cash status, and repeat failures can be viewed together, patterns that are easy to miss in separate systems become much more visible.
The Cost of Static ATM Cash Management
Cash availability is fundamental to ATM performance. Yet many ATM networks still rely heavily on fixed replenishment schedules, static thresholds, or historical averages that do not respond quickly to changing demand.
The weakness in that approach is straightforward: ATM demand is not static. A Tuesday before payday may behave differently from the following Tuesday, while a normal weekend can look nothing like a holiday weekend. A local festival, sporting event, weather disruption, benefit payment, or temporary closure of another nearby cash point can materially change withdrawals at an individual terminal, and a forecast built only around a simple historical average can miss those changes.
Cash-Outs Are Only One Side of the Problem
When cash forecasting underestimates demand, the result is obvious: the ATM runs out of cash. That creates an immediate availability problem, may require an unscheduled CIT visit, and can result in lost transaction volume during the period the machine cannot dispense.
For an off-premise terminal, repeated cash-outs can affect more than the economics of the machine itself. The retailer or site owner may see the ATM as unreliable, while customers learn that the location cannot be depended upon for cash.
Overestimating demand creates a less visible problem. The ATM remains available, so the operational dashboard may look healthy, but excess cash sits idle inside the network instead of being used elsewhere. Across hundreds or thousands of terminals, relatively small overestimations at individual ATMs can add up to significant residual cash.
This is sometimes described as "sleepy cash": money positioned in the network but not actually required to support withdrawals. The goal is therefore not simply to prevent cash-outs, but to balance availability against the amount of cash deployed across the estate.
Dynamic Forecasting Changes the Replenishment Decision
Dynamic, ATM-level forecasting provides a better basis for that decision because it considers expected demand at the individual terminal rather than treating every machine as if it follows the same pattern.
Useful forecasting can incorporate factors such as:
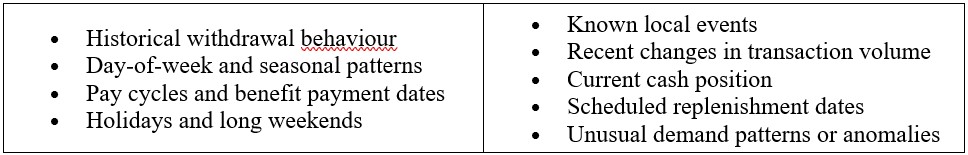
The operational value comes from combining the forecast with the replenishment plan. A low balance is not necessarily an exception if forecast demand indicates the ATM has enough cash to reach its next scheduled visit. Conversely, an ATM that has not yet crossed a traditional low-cash threshold may still require attention if forecast demand suggests it will cash out before the next CIT run. That is a much more useful definition of "low cash."
Cash Forecasting and CIT Planning Should Not Be Separate Decisions
Cash forecasting is only useful if it changes operational decisions. Knowing that a terminal is likely to cash out in 36 hours does little good if that information remains disconnected from CIT scheduling.
This is one of the common structural problems in ATM operations: forecasting identifies a requirement, while another team or provider separately manages the movement of cash. When those workflows are disconnected, operators can end up solving individual cash problems in expensive ways.
An emergency replenishment may protect availability but carry a significantly higher service cost. Moving one visit may also affect other stops on a route, so a decision that looks sensible at the individual ATM level may be inefficient across the wider network.
Better fleet management therefore considers two questions together: How much cash will this ATM need, and what is the most efficient way to get that cash there? The answer may be to move a visit forward, increase the amount delivered on the next scheduled visit, or leave the ATM untouched because its existing balance is sufficient. The objective is not simply fewer CIT visits; it is better-timed visits.
The Disconnect in Field Service Coordination
Finding a fault is relatively easy. Resolving it efficiently is where operators often lose time and money. Service requests may pass through monitoring systems, internal operations teams, emails, ticketing platforms, FLM providers, SLM providers, and manufacturer support channels, and every handoff creates an opportunity for context to disappear.
A technician may receive a ticket containing a terminal ID and a generic fault code without knowing that the same fault has already occurred several times. The technician resolves the immediate symptom, closes the ticket, and leaves, only for the ATM to fail again two days later. From a ticketing perspective, two incidents were successfully closed; from an operational perspective, the problem was never solved.
First-Time Fix Rate Matters
This is why first-time fix rate should be considered alongside mean time to repair (MTTR). A fast repair is valuable, but not if the same fault returns shortly afterwards.
A strong service workflow should give the technician enough context to understand what has happened previously. That can include:
• Previous fault codes and repeat failures on the same module
• Prior service calls and recent FLM or SLM activity
• Parts that have already been repaired or replaced
• Technician notes and previous escalation history
• Relevant SLA timing and response requirements
If a component has already been replaced twice during the quarter, the third related failure deserves a different response from the first. The operational objective is not simply to close a service ticket quickly, but to restore the ATM properly and reduce the probability of another avoidable outage.
FLM and SLM Dispatches Need Better Information
Incorrect dispatches are another source of unnecessary cost and delay. If an FLM technician is sent to a problem that requires SLM expertise, the first visit may do little more than confirm what could potentially have been identified from the fault history. The ATM remains unavailable while another dispatch is created, which is particularly damaging when contractual SLA clocks are running.
Better service coordination uses available fault data and historical context to improve the quality of the initial dispatch. The system does not need to diagnose every hardware problem automatically to create value. Even identifying repeat patterns and giving operators better information before assigning the call can reduce unnecessary handoffs.
Vendor Accountability Requires a Shared Operational Record
ATM networks often depend on multiple external providers, making accountability difficult when the data needed to reconstruct an incident is spread across several organisations. Consider a prolonged outage involving a monitoring provider, FLM vendor, SLM provider, and CIT company. One vendor may say the fault was escalated late, another may say the wrong fault information was supplied, and a technician may report that a required part was unavailable. Operations may believe the original call should have been classified differently.
Without a shared chronology, the discussion quickly becomes subjective. A stronger fleet management model creates an operational record of what actually happened:
• When the issue was detected, logged, and acknowledged
• Which provider received the ticket and when a technician was dispatched and arrived
• What work was performed and whether the issue was resolved
• Whether the fault recurred or required another service call
• Which SLA conditions and response requirements applied
This turns vendor management from anecdotal performance discussions into measurable operational performance. It also makes SLA reporting more meaningful because, instead of simply knowing that a provider missed a target, managers can identify where delays occur and whether the same problem is recurring.
The Challenge of Managing Mixed ATM Estates
Very few large ATM networks remain technically uniform forever. Acquisitions, phased upgrades, geographic expansion, contract changes, and long hardware replacement cycles naturally create mixed estates.
An operator may be managing different manufacturers, models, operating systems, monitoring technologies, and service agreements simultaneously, with the oldest terminals potentially installed under an entirely different operational model from the newest ones. This creates two challenges: visibility and lifecycle management. Different machines and systems may report information differently, making it difficult to establish consistent performance metrics across the fleet, while different generations of equipment may have very different maintenance and replacement requirements.
Fully Depreciated Does Not Mean Free
Older hardware can appear economical because the original capital cost has already been depreciated, but depreciation is an accounting measure rather than an operational health metric.
An ageing ATM may require increasingly frequent service calls, replacement components may become more expensive or difficult to source, and older software may create additional support requirements. Repeat outages can also reduce transaction volume and increase vendor costs, meaning individual repair invoices may hide the true cost of keeping the machine in service.
A more useful lifecycle view combines factors such as:
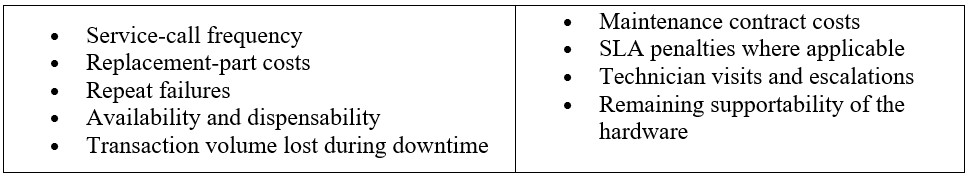
Taken together, these factors can help operators identify when a terminal is shifting from "cost-effective to repair" toward "increasingly expensive to maintain."
Replacement Decisions Should Be Evidence-Based
Hardware replacement programmes often compete for capital with many other priorities, making objective fleet data especially important. Rather than replacing machines primarily according to age, operators can use performance and cost data to identify which terminals create the greatest operational burden.
Two ATMs installed in the same year may have very different replacement priorities. One may continue operating reliably with minimal maintenance, while another may experience repeated component failures, extended downtime, and declining transaction availability. Age provides context, but operational performance provides a stronger business case.
Moving from Monitoring to Exception-Based ATM Management
Large ATM fleets generate an enormous amount of operational data, so the challenge is no longer simply collecting it but deciding what deserves attention. If an operations team must manually scan dashboards and reports to identify problems, scale works against them. As the fleet grows, the number of alerts grows with it until important conditions begin competing with routine information for the same limited attention.
Exception-based management changes that model. Instead of asking operators to continuously search for problems, the system identifies conditions that fall outside defined operational parameters and brings those situations forward for action.
Not Every Alert Is an Exception
The distinction between an alert and an exception is important. An alert tells you that something has happened, while an exception identifies a condition that requires attention.
For example, an ATM crossing a predefined cash threshold may generate an alert. But if the terminal still has enough cash to cover forecast demand until tomorrow's scheduled CIT visit, there may be nothing for the operator to do, and escalating it simply creates noise.
By contrast, a terminal may still sit above its normal low-cash threshold but be projected to cash out before the next visit because withdrawal demand has increased sharply. That is an operational exception. The same principle applies to maintenance: an isolated error that clears itself may be worth recording but not escalating, while the same error appearing repeatedly on a machine with a recent history of related failures may justify immediate investigation.
Exception management is therefore not about creating more alerts. It is about making fewer, better alerts so operators can focus their attention where intervention is most valuable.
Connecting Cash, Service, and Availability
One of the biggest opportunities in ATM fleet management comes from examining operational data together rather than by function. Cash management and maintenance both affect availability, CIT performance affects cash availability, service quality affects maintenance cost, hardware age affects service demand, and transaction volume affects the economic impact of downtime. These are interconnected operational factors, not independent categories.
Consider an ATM with declining transaction volume. Viewed in isolation, that might look like a demand issue, but the picture changes if the machine has also experienced several short dispenser outages or repeatedly cashed out during peak periods. Customers may simply have learned to use another ATM.
Similarly, a terminal with high servicing costs may still justify those costs if it generates significant transaction value and serves a strategically important location. The purpose of consolidating operational data is not to create a larger dashboard, but to make these relationships easier to understand. That is the difference between data visibility and operational intelligence.
What to Demand from an ATM Fleet Management Platform
Operations budgets rarely grow at the same pace as operational complexity, which means technology has to do more than display data. It should help teams prioritise decisions, coordinate workflows, and understand what is happening across the estate without forcing users to investigate every issue manually.
When evaluating an ATM fleet management platform, several capabilities deserve close attention.
1. Centralised Visibility Across a Mixed Estate
A platform should provide a consistent operational view across different ATM manufacturers, models, and supporting systems where integrations allow. The objective is not necessarily to replace every piece of existing infrastructure, but to reduce the number of separate systems an operator has to consult before understanding the state of the fleet.
2. Exception-Based Monitoring
Operators should be able to define meaningful conditions and prioritise situations requiring intervention. A platform that simply consolidates thousands of alerts into one screen has centralised the noise without solving the underlying problem; the value comes from turning data into prioritised operational exceptions.
3. ATM-Level Cash Forecasting
Forecasting should operate at a level that reflects the behaviour of individual terminals. Network-wide averages are useful for reporting, but replenishment decisions occur at individual cash points. Forecasting should therefore help teams understand expected demand, identify potential cash-outs before they occur, and avoid unnecessarily high cash holdings.
4. Integration Between Forecasting and CIT Activity
Cash forecasting and replenishment planning should inform each other. Operations teams should be able to compare projected demand against current balances and planned visits rather than working from disconnected datasets. This makes it easier to identify where a scheduled visit can remain unchanged, where a visit may need to move, and where replenishment quantities may need adjustment.
5. Service History and Workflow Integration
Fault information becomes much more useful when it is connected to service history. Operators and technicians should be able to see whether an incident is new or part of a recurring pattern, providing context that can improve dispatch decisions, escalation, root-cause investigation, and first-time fix performance.
6. SLA and Vendor Performance Tracking
The platform should make it possible to measure provider performance against actual contractual expectations, including response times, arrival times, resolution activity, repeat visits, and other relevant service events. Without that information, SLA management risks becoming a monthly reporting exercise rather than an operational management tool.
7. Lifecycle and Cost Visibility
Fleet managers should be able to identify terminals that consume disproportionate service resources or experience recurring availability problems. Combining maintenance activity, downtime, and operating cost creates a stronger basis for repair-versus-replace decisions.
8. Operational Reporting That Supports Action
Reports should answer operational questions rather than simply summarise activity: Which terminals repeatedly cash out? Which machines generate the most repeat service calls? Which provider is missing response targets? Which ATMs carry consistently excessive residual cash? Which terminals have deteriorating availability despite apparently acceptable uptime?
Answering questions like these helps managers improve the estate because the reporting is tied directly to operational decisions.
The Sonas Approach to ATM Fleet Management
The Sonas approach is built around bringing operational information together so teams can manage ATM fleets with greater context. Rather than treating cash management, service activity, forecasting, and vendor performance as separate operational problems, the objective is to connect the information needed to understand what is happening across the physical cash environment.
For ATM operations teams, that can mean moving from manual monitoring toward exception-based workflows, using cash forecasting to support replenishment decisions, maintaining better visibility into service history, and measuring third-party performance more consistently.
The practical test of any platform is whether it helps connect the dots. If an ATM cashes out after a delayed CIT visit and has also experienced recurring hardware problems, how much investigation does the operations team need to perform before understanding the sequence of events? If answering that question requires logging into three systems, exporting two reports, and emailing a vendor for additional information, the data may exist, but the operational context does not. That is the blind spot ATM fleet management needs to solve.
The challenge for modern ATM operators is not a lack of data; most networks generate more data than their teams can realistically investigate manually. The challenge is converting that data into context that supports better decisions.
For organisations managing complex ATM estates, improving fleet performance therefore starts with connecting cash, servicing, availability, forecasting, and vendor activity around the decisions operations teams make every day. Sonas Systems brings these areas of physical cash operations together to help organisations move from fragmented monitoring toward more proactive fleet management.
Contact Sonas Systems to discuss how a more connected approach could support your ATM network.
Frequently Asked Questions About ATM Fleet Management
What is ATM fleet management?
ATM fleet management is the coordinated monitoring and operation of a network of ATMs. It can include terminal availability, cash forecasting, replenishment planning, CIT activity, maintenance workflows, service history, SLA management, vendor performance, and hardware lifecycle decisions. The objective is not simply to keep machines online, but to keep terminals operational and able to complete customer transactions while controlling cash, servicing, and vendor costs.
Why isn't ATM monitoring software enough to prevent cash-outs?
Basic monitoring can tell an operator how much cash an ATM currently holds, but that does not necessarily indicate whether the machine has enough cash to reach its next scheduled replenishment. Preventing cash-outs requires combining current cash balances with expected withdrawal demand and CIT schedules, with forecasting providing the missing time dimension: not just how much cash is available now, but how quickly that cash is likely to be used.
What is the difference between ATM uptime and dispensability?
Uptime generally indicates whether an ATM is technically online and connected, while dispensability focuses more specifically on whether the ATM is actually able to dispense cash and complete the transaction the customer needs. An ATM can therefore appear "up" while being unavailable for withdrawals because of a cash-out, dispenser problem, presenter fault, or another issue. For operations teams, the distinction helps create a more realistic picture of customer-facing availability.
How can ATM operators reduce CIT costs without increasing cash-out risk?
One approach is to move away from purely static replenishment schedules and use ATM-level forecasting to determine when cash is actually required. Low-volume terminals may be able to operate longer between visits, while high-volume terminals may need earlier or larger replenishments. The goal is not simply to reduce the number of CIT visits, but to align visits more closely with expected demand while maintaining appropriate cash availability.
How can operators improve ATM first-time fix rates?
Technicians need more than a current fault code. Providing access to previous faults, service history, parts replacements, repeat failures, and previous technician notes can help determine whether the current incident is isolated or part of a recurring problem. Better context can also help operations teams decide whether the initial dispatch should go to FLM or SLM, reducing unnecessary handoffs and repeat visits.
How can ATM operators improve vendor accountability?
A central operational record can document when a fault was detected, when the service request was created, when the vendor acknowledged it, when the technician arrived, what action was taken, and whether the fault subsequently returned. This creates a clearer basis for measuring vendor performance against SLAs and investigating recurring service problems.
How do you know when an ageing ATM should be replaced?
Age alone is not enough. Operators should consider the terminal's total operating profile, including service-call frequency, parts costs, recurring failures, downtime, transaction impact, maintenance expense, and hardware supportability. A fully depreciated ATM can still be expensive to operate if it requires frequent repairs or creates repeated availability problems.
What metrics matter for ATM fleet performance?
The appropriate metrics depend on the network and operating model, but useful measures can include dispensability, first-time fix rate, MTTR, forecast accuracy, cash-out frequency, residual cash, CIT activity, repeat service calls, SLA performance, and maintenance cost by terminal. The most useful metrics are those that help explain operational outcomes and support decisions rather than simply describing activity.